We always believe that the most valuable signals regarding the progress of AGI must come from those who are directly advancing it. The market and valuations reflect expectations, while the explorations of researchers determine which possibilities will become reality.
What interests us most are young researchers, for whom many practices already familiar in various industries can still be questioned as to why. We hope to engage in such collisions of thought, discussing the research they are conducting, as well as the directions they believe are worth betting on that have not yet been fully discussed.
Two weeks ago, we invited AI researchers from various model vendors for an offline closed-door discussion. From Astra's Computer Use, to RSI, model distillation, and training data, everyone shared specific research experiences and proposed differing judgments: which advances might be underestimated, which bottlenecks may be harder than expected, and where the next breakthroughs might occur.
We have extracted the publicly shareable insights from this discussion, preserving its consensus and disagreements, to share with friends who are concerned about model advancements, and we look forward to more friends joining the discussion.
| | / | |
Insight 01
What does the improvement in Astra's Computer Use capabilities mean?
1. The most noticeable change in usage of Astra is that the agent can complete tasks in more software. Although agents were already able to handle considerable work in Obsidian and GitHub before the release of Astra, in relatively complex software like Blender, game engines, and Excel, the last few steps often required human intervention. After the enhancement of Astra's Computer Use capabilities, agents now operate tasks through software interfaces more smoothly.
2. Computer Use also gives agents the opportunity to use software that does not provide complete interfaces. For example, LinkedIn may not be willing to expose all information through APIs, as it may affect its platform's commercial value; enterprise internal business systems like Salesforce often require special integration to exchange information with one another, and many old software systems are difficult to update individually with CLI or API interfaces. However, with Computer Use, as long as human users can see and operate the interface, the agent has the opportunity to perform the same actions.
3. The improvement in Astra's Computer Use capability is not a sudden achievement, but rather the result of OpenAI's long-term investments. Unlike domestic efforts, leading overseas model vendors maintain large GUI teams, with related investment levels second only to Coding; while some domestic teams have reduced GUI investments and shifted towards Coding. Thus, new models becoming user-friendly may reflect the culmination of past investments rather than arising from a single technological breakthrough.
4. However, the advancement of Computer Use capabilities does not imply a corresponding enhancement in the model's general visual understanding:
• Software and screen operations have relatively regular layouts and clear buttons, meaning operational objectives are clearer, making these tasks easier for models to train and validate compared to general image understanding;
• Just because a model can operate a software interface does not mean the agent's operations are sufficiently stable. An example is e-commerce pop-ups, where the position and style of pop-ups frequently change; while humans typically know to look for the close button in the upper right corner, models may repeatedly make errors.
• One countermeasure is to have humans incorporate experience into prompts, or store it in memory and invoke it through a harness responsible for executing processes, which can reduce some errors. However, how to summarize experiences and when to call upon them are typically still designed by humans, and changing the interface can render this ineffective. Therefore, for models to adapt to unseen interfaces, they need to derive experiences from interactions and judge when they are applicable.
5. Whether models can accumulate experience will also affect enterprises’ willingness to modify their systems for them. In considering this matter, enterprises will look not only at the speed at which the agent executes tasks and resource consumption, but also at how much human involvement is required for each complete task by the agent. If after 3-5 rounds of human feedback an agent can reduce repeated errors, enterprises will be more willing to invest resources in facilitating the agent's interfaces; if the same issues need human handling every time, it becomes difficult for enterprises to assess the potential returns of modifying their systems for the agent.
6. In the long term, there is still disagreement over whether Computer Use will remain important:
• For platforms like shopping and food delivery, aiming to attract orders generated by agents, they will gradually open CLI and API, and AI Coding has also reduced the costs of system modifications. Once interfaces are opened, agents can directly call software services without needing to click through interfaces incrementally. Therefore, agents' reliance on GUI may peak during the transitional period before declining. This is similar to mixed traffic between human drivers and autonomous vehicles, where the traffic is more complex; once all vehicles switch to autonomous driving, coordination may actually become simpler.
• There are many legacy systems, and new software may not prioritize AI. Even if more platforms open their interfaces, agents will still need to operate those systems that cannot be directly called upon through Computer Use.
Insight 02
How far is agent autonomous execution of tasks from true RSI?
7. When agents can execute more software tasks, the next question is whether AI can further participate in model development, i.e., RSI.
8. A current early practice of agents in model development is that when model vendors enter a new domain, they often need to determine benchmarks, find data, set up environments, and conduct training. To cope with the increasing number of domains and limited manpower, some teams have started to experiment with letting agents execute processes designed by humans in advance, thereby taking over some of the work of ML engineers.
9. Other teams have stored operational methods for model development as shared skills for colleagues and agents to refer to. At that time, they had not yet trained these experiences into model parameters, but this shared system led to reduced efficiency in development. The underlying problem is that models cannot distinguish which records apply to the current task; therefore, sometimes agents may blindly mimic methods used by colleagues for other tasks and only discover after a long time that they weren't performing the task required by the user.
But having agents execute fixed development processes does not equate to RSI
10. Having agents execute fixed development processes does not truly realize RSI, as the data, workflows, and evaluation criteria are still primarily designed by humans.
11. Some vendors only provided computational power to code agents, allowing them to generate their own data, but did not observe sustained improvements in the model’s capabilities. Even after adding network search capabilities to the model, issues still remained unresolved.
12. To truly achieve RSI, agents must be capable of determining what to change based on experimental results, which experiences are worth reusing, and advancing subsequent model development. To achieve this effect, models must be able to make developmental judgments, requiring an understanding of model training methods and corresponding experimental results.
13. As for how to enable agents to independently push forward experiments, there are viewpoints suggesting that the post-training experiences of cutting-edge large models are seldom made public, so models might not have learned the latest methods or be able to autonomously supplement this knowledge. Therefore, models might still need humans to provide relevant knowledge.
14. But can weaker models supplement corresponding knowledge through autonomous exploration and further train to develop stronger models? On this point, different people have different views:
• One viewpoint holds that a lack of knowledge could reduce exploration efficiency. For example, in board games with well-defined rules and victory conditions, models can adjust based on feedback, but “surpassing GPT-6” has numerous possible development paths, and models may not know which path to attempt. Directly supplementing development knowledge can help models find direction within limited time and resources.
• Following this viewpoint, even if weaker models increase their attempts, it does not mean they will necessarily fill the knowledge gap. One hypothesis is that although leading models can find a proof path for a certain mathematical problem, a weaker model may try a million times without success, and thus retraining based on these failed attempts may not effectively teach the weaker model useful methods.
• Another viewpoint posits that the current knowledge of models does not equate to their upper limits. RSI is intended to allow models to acquire new knowledge through exploration and improve development methods; starting from a weaker point does not mean it cannot train to develop stronger models.
15. There is still no consensus on whether the question of "whether humans breaking down the goals a model needs to achieve reduces the requirements for RSI" can be resolved. Essentially, changing "surpassing a certain model" to "exceeding it on several benchmarks" means humans have already made part of the judgments on behalf of the model.
• One perspective suggests that at this stage, we can first verify whether models can automatically find data and complete training, and then gradually allow them to break down more ambiguous objectives.
• Another viewpoint contends that breaking down objectives should inherently be the model's responsibility. Pre-selecting benchmarks by humans equates to injecting their experiences into the model in advance, meaning that what the model is actually verifying is an easier problem.
Kernel optimization may be the most suitable scenario to first realize RSI
16. Kernel optimization tasks may represent one of the most suitable scenarios today for initially achieving RSI. Kernels are programs that execute calculations on GPUs, with the optimization goal of improving execution speed under specific computational tasks and input sizes.
• The advantage of this type of task is that feedback is direct: modified code can be run directly on the GPU to see if performance improves, and optimization can continue based on test results.
• At the same time, model vendors clearly know which computational tasks need optimization and have engineers familiar with GPU programming; related internal experts can provide specialized knowledge directly.
17. The optimized kernels still need to connect to the actual training system to confirm computational results are accurate and can cooperate with other modules to genuinely save resources and accelerate experiments. There is currently divergence in assessment of how difficult this step is.
• One viewpoint posits that optimizing specific inputs with definitive models makes connection issues relatively controllable.
• Another viewpoint is more concerned with numerical consistency, module compatibility, and corner cases not covered in testing.
18. A longer-term vision is that after providing model structures and computational requirements, AI can directly generate GPU code, reducing reliance on compilers and intermediate representations, thereby decreasing the conversion processes from high-level descriptions to executable code, and even further designing dedicated chips for the model.
Insight 03
What are the difficulties in model distillation?
19. In simple terms, model distillation involves collecting the outputs or inference processes of a teacher model and using these data to train a student model. However, a notable trend with Astra and Fable 5 is that OpenAI, Anthropic, and others have begun investing in defenses against distillation, leading to market concerns over whether it has indeed become more challenging.
20. The primary engineering difficulty of distillation lies in stabilizing the output of sufficient usable data:
• Extracting one or two samples occasionally is a different requirement for infrastructure and cost compared to producing ten thousand stable records. The accuracy of data restoration, whether 70% or 99%, also influences how many samples can ultimately be used for training.
• During data collection, it is essential to thoroughly restore the CoT and eliminate anomalous content. Some samples may provide correct answers, but have issues with CoT, meaning one cannot solely check the final answer. Cleaning this data is also part of the distillation cost.
These anomalies may stem from interference in the teacher model's outputs or errors during the collection process, such as missing a round of dialogue, failing to reconstruct compressed content fully, or introducing unrelated tokens.21. The same batch of teacher data may yield different results when training various student models. The size and inherent abilities of the student models, as well as the training infrastructure, personnel, and training recipes of their teams, will affect the final training outcomes.
Some teams have long used data from a single teacher model, but when mixed with CoT from other models, the training effectiveness noticeably declined. Therefore, when changing data sources, teams may also need to adjust their training methods simultaneously.
22. Distillation also faces timeliness issues: even when teacher data is ultimately secured, it may not keep pace with model iterations.
• One assessment is that as long as the teacher model continues to provide an API, teams will always find ways to continue distillation.
• Another perspective suggests that in the future, the cycle required to find distillation methods and stabilize data production may noticeably lengthen, making the ability to collect data as crucial as the timeliness of acquiring sufficient data for model development.
Insight 04
What constitutes "good data"?
23. Recently, there has been a clear trend in both China and the United States where human data provided by experts is becoming an increasingly important source for model training, as the value of this data lies in assisting models in achieving results that users are willing to pay for.
• In many vertical fields, much of the know-how related to how professional materials are organized and how judgments are presented is familiar to practitioners but is not fully documented online.
• Additionally, benchmarks in certain vertical fields often only cover the initial steps of real work and do not encompass subsequent processes. To train models to complete entire tasks, someone must define the objectives, fill in the context, and clarify what results qualify as satisfactory.
24. Today, model vendors globally are hiring professionals from various fields to participate in the production of specialized data. As training pipelines become standardized, individuals without ML backgrounds also find it easier to engage in generating questions and providing feedback, and can even assist teams in finding product testers. Model developers can also enter industry settings to gain a direct understanding of work processes.
25. Anthropic, for example, allows individuals with different professional backgrounds to use internal models and organizes developers to experience work at investment banks like JPMorgan, giving them a more intuitive grasp of work processes and clarifying where models can provide assistance.
26. Having industry experience does not mean one can directly generate data; even experts familiar with the jobs need to learn how to break down tasks, prepare contexts, and design evaluations. In one business case, operators familiar with data production processes could generate dozens of questions within a week, while experts might only manage a few, or even temporarily be unable to produce satisfactory questions.
27. Converting expert experience into training data also encounters two challenges: whether experts can articulate the basis for their judgments and whether task results can be verified promptly.
• Some people do excellent work, but struggle to explain why they make certain judgments; thus, having them engage in specific tasks, document the processes, and check them against results is often the best way to identify effective experiences.
• Investing in such work often requires a long wait to see results, making it difficult for models to receive timely feedback and training signals. One viewpoint suggests that as continual learning matures, models may be able to accumulate experience and utilize long-cycle feedback, thereby making invested experience easier to incorporate into training.
28. Overall, to utilize specialized task data for RL, suppliers need to provide tasks, work environments, and evaluation methods simultaneously, allowing models to experiment repeatedly and obtain training signals based on outcomes. Complete RL data should include at least the following four components:
• Task: Clearly delineate what task the model must complete;
• Context: Provide necessary documents, data, or application environments;
• Metric: Specify how results are to be evaluated and scores calculated;
• Reference Answer: Provide a result for the model to reference that does not require exact matching.
29. Besides needing to be comprehensive, "good data" must also meet the requirements that its content is correct and that the customer's training system can utilize it. Errors in content or files exceeding the system's processing capabilities can prevent real tasks from entering training directly.
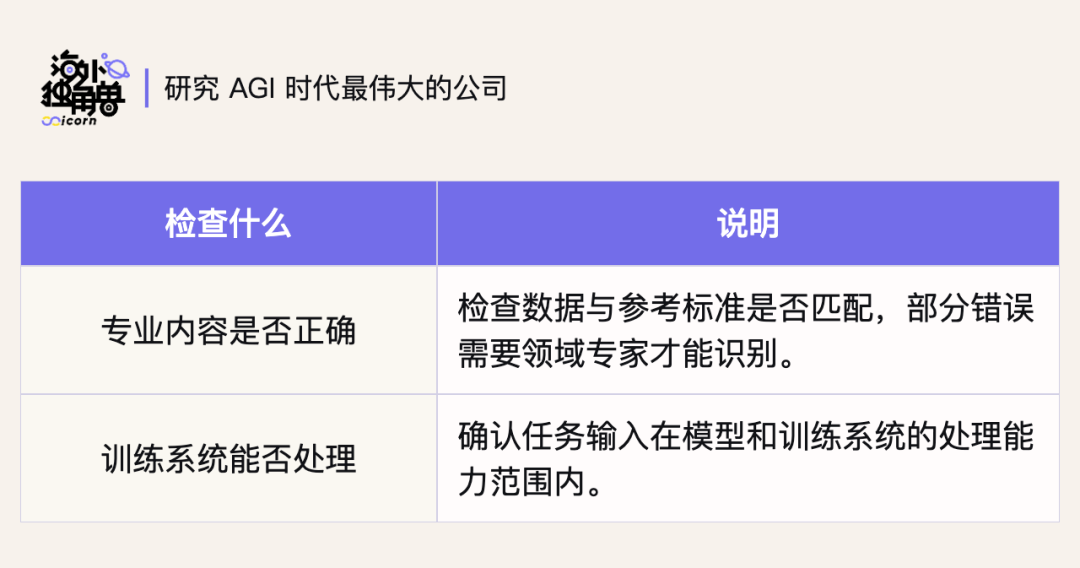
30. Model vendors need to balance model capabilities, the number of attempts allowed per task, and training methods when selecting data, striking a balance between task difficulty and learning value.
• If the model has limited attempts per task, simpler tasks that allow the model to achieve successful feedback should be chosen; if the model can attempt more times, difficulty can be appropriately increased.
• Different training methods also have varying data requirements: some stages of model training can utilize larger scales of off-policy data; other stages may be better suited to use trajectories generated by the current model itself and can repeatedly attempt around smaller datasets.
31. After completing these checks, the actual training benefits brought by the data still need to be verified on the target model. Vendors can start with small models for small-scale experiments before validating with larger models. It is vital to note that even if suppliers have validated data effectiveness on open-source models, clients may not be able to replicate this, as the base models' capabilities, training data distributions, algorithms, and infrastructures may differ.
32. When validating training benefits, it is essential to differentiate whether models can learn the current tasks and whether the skills acquired can be applied to other tasks.
• In some training attempts related to Genshin Impact, Honor of Kings, Go, and Dou Di Zhu, tasks required reasoning, and although experts could document full CoTs, the outcome demonstrated that the model struggled even with fitting the training set itself. This indicates that professionals might articulate reasoning clearly, but it does not guarantee the model can learn.
• Some training experiences also indicate that coding data can enhance models’ performance on tasks with significant discrepancies and that learning to complete long tasks involving multiple effective interactions can further improve performance on some short or different types of tasks.
33. Although improving benchmark scores does not necessarily enhance user experience, some teams have discovered that when models enhance their scores across enough diverse benchmarks, even without specifically optimizing experiences, users' actual experiences can improve.
• One explanation is that these benchmarks include numerous instruction-following requirements, such as accurately parsing CSV and JSON, and related training can simultaneously improve both coding and downstream task capabilities, thereby reflecting on user experience.
• Some benchmarks may also compel teams to enhance the model's fundamental capabilities. For example, during a long-horizon task test requiring multiple continuous steps, some teams attempted targeted optimizations for this test but were unsuccessful, ultimately having to seek more fundamental model improvement methods.
34. Finally, when evaluating model performance, one must also examine the cost associated with completing model tasks. For the same question, the token usage across different models may differ by tenfold or more. However, from a training priority perspective, teams often first challenge the model with difficult questions before reducing the token usage required to complete tasks.
Insight 05
How to conduct data business amid rapid model iterations?
35. Just because data has training value does not mean vendors can continuously obtain orders. Model vendors must first decide which data they can develop themselves and which they should procure externally. Both can complement each other: internal teams typically have a better understanding of the models, while external procurement can supplement internal data and validate whether it can bring additional benefits.
36. Among these, the records left by users after interacting with models, or the return data obtained by model vendors, will determine whether they can replace external procurement, depending on task data distribution and filtering costs; total volume alone is not sufficient.
• If users mainly use models for entertainment, the return records may lack tasks related to finance, law, healthcare, and so forth. External custom procurement can supplement scenarios not yet covered by existing users.
• Even when user usage records contain tasks needed to improve models, it can sometimes be more expensive for model vendors to filter through vast interactions to extract useful training signals than directly customizing data.
37. Model vendors often utilize externally purchased data as the first batch of samples when models enter new domains to understand task requirements before building their own data synthesis pipelines. The key specialized knowledge still needing external supplementation leads teams to continue procuring data.
• One assessment suggests that once model vendors catch up with SOTA models by about 80-90% in coding abilities, they might look for new high-value tasks. Experts in coding and kernel optimization often reside within the vendor’s own teams, whereas expert knowledge in finance, law, and healthcare typically requires external acquisition, presenting opportunities for data suppliers.
• Distillation can also influence procurement willingness. With clear teacher models, teams can chase improvements through distillation; when distillation returns diminish and exploratory new directions are needed, suppliers have greater chance to provide new tasks and data.
38. External procurement can also support model vendors in coping with demand fluctuations. For instance, if a model unveils shortcomings on a specific benchmark, teams may require ten thousand data points within a week. If the internal data team is staffed based on peak demand, they may often have idle time; if they staff according to average demand, they may struggle to handle unexpected tasks. External suppliers can allocate personnel across clients, allowing for more flexible capacity arrangements.
39. Self-built and externally procured data also face different quality constraints. If a supplier's data does not meet standards, clients can reject acceptance and payment; internal teams mainly rely on performance and organizational management. Frontline observations indicate that, in model vendors’ settings, when model capabilities improve, credits are often attributed to researchers, making it difficult to precisely measure the contributions of data teams; even if data positions produce more and better data, they may not receive immediate rewards.
40. Therefore, for data suppliers to secure orders, they first need to understand clients' training objectives. Some model vendors emphasize benchmarks, while others prioritize experience and commercial value, but clients usually do not initially disclose complete model information. One approach is to provide finished tasks for clients to filter by type and difficulty, accumulating trust before developing data around tasks where the model performs poorly (Bad Cases).
41. Based on frontline observations, frontier labs may propose data needs 3-6 months prior to model release, with some areas even planning about twelve months ahead; suppliers need to prepare in advance, but the data produced may not remain sellable for long: once models can autonomously generate such data, procurement needs may decrease.
• This implies that suppliers need to find task executors in advance and support 6-12 months of preliminary research with their cash flow, similar to betting on a short drama’s potential success, which carries the risk of demand fluctuation.
• However, suppliers can also refer to model vendors’ capability targets and development plans to arrange preliminary research; even if some data batches become obsolete, the accumulated expertise, task knowledge, and production processes can be utilized for developing the next batch of data.
42. In the data market, just because a supplier is large does not mean they can excel in every field. For instance, overseas, although Surge AI and Mercor are already substantial, new teams might still win orders by providing in-depth understanding and appropriate specialists for certain types of tasks.
• One assumption is that a smaller team dedicated to a rare specialty task may generate data needed by large clients, which might lead to big clients spending ten million dollars to outright purchase a year's production from that team.
• Model vendors may also become data suppliers, but algorithm personnel may not be inclined to commercialize their research outputs.
43. The price of data depends on task difficulty, task diversity, actual training effects, and exclusivity of sale.
• Non-exclusive procurement is relatively common domestically, with a batch of data typically resold approximately two to three times, spreading costs across multiple sales.
• Exclusive prices can be several times that of non-exclusive ones, and suppliers need to tightly manage exclusive data, preventing sold data from being copied or resold.
44. In the future, as work methods continue to evolve, new data needs may also arise.
• For example, tasks previously completed with Excel may later use HTML or other tools, and the usage of SQL databases could also change. If models cannot autonomously adapt to these changes, there will be a need to supplement new training data.
• Suppliers are also considering changing data sources. One long-term vision is for data suppliers to operate work platforms themselves, allowing users to leave tasks and feedback while using AI, and subsequently converting these records into RL data.
45. Existing business processes and work records within enterprises could also be organized into RL environments, allowing models to execute tasks and receive assessments in situations that closely mirror real company environments. For instance, companies might combine records saved in DingTalk/Feishu with explanations from former employees to reconstruct task contexts, decisions, and business issues, providing materials for establishing training environments. The capabilities that models gain through training with these data can also be utilized in other enterprises.
46. Therefore, the business domain of data suppliers may also extend to enterprise AI deployment. For example, some corporate clients may require private models, proprietary data, and private deployments, allowing data suppliers to assist these clients in streamlining operations, determining which tasks are suitable for AI, and completing engineering deployments. Such services can follow an FDE model, enabling engineers to delve into client businesses and facilitate adaptations. The vendor's customer base may also expand from about twenty foundational model vendors to include more medium and large enterprises.
| | | |
免责声明:本文章仅代表作者个人观点,不代表本平台的立场和观点。本文章仅供信息分享,不构成对任何人的任何投资建议。用户与作者之间的任何争议,与本平台无关。如网页中刊载的文章或图片涉及侵权,请提供相关的权利证明和身份证明发送邮件到support@aicoin.com,本平台相关工作人员将会进行核查。


